From One Box to a Cluster: Building Homelab HA with Proxmox, ZFS, and a Lot of Patience
There's a certain stage in every homelab journey where optimism stops being a strategy. For a long time, my single Dell OptiPlex running Proxmox was a calculated bet: the hardware was small, efficient, and had never failed me. I kept backups. I had PBS. If something went wrong, I could restore in 15–30 minutes. That felt acceptable.
Then I had a double disk failure during a migration. Not a single disk — two, simultaneously, while I was in the middle of moving data. I got lucky. Nothing was permanently lost. But the experience crystallised something: my reliance on the homelab had grown well beyond what a single-node setup could responsibly support. Hermes, my AI agent, lives there. My DNS, my reverse proxy, my camera NVR — all of it was on one box. One hardware failure away from being completely dark.
The disk failure wasn't a reason to panic. It was a reason to fix things before the next incident rather than after. So I bought a second machine, added it to a shelf, and eventually spent a very long day turning my single-node Proxmox into a proper two-node HA cluster with ZFS replication. This post is the full story of how that went — the plan, the pivots, the gotchas, and the final state.
The Hardware
The second node is an HP EliteDesk 800 G5 Mini — a small form-factor machine with an Intel Core i5-9600 (6-core, 9th gen), 32 GB DDR4, and a 256 GB SSD. I picked it up for around $200 AUD. It sits next to the OptiPlex on the same shelf, connected to the same switch.
Why does the CPU generation matter? Because Proxmox live migration requires the same CPU microarchitecture flags on both nodes. The i5-9600 and the i7-9700T in the OptiPlex are both Skylake/Coffee Lake 9th gen — same flags, live migration just works without any custom CPU masking.
Before installing anything, I went into the HP BIOS and verified:
- VT-x (virtualisation) → enabled
- VT-d (IOMMU) → enabled
- Secure Boot → disabled
- Legacy Support → disabled (UEFI only)
For the Proxmox install, I used Rufus in DD Image mode (not ISO mode — DD is the correct choice for Proxmox ISOs). The one key decision during install: the ZFS pool name. More on why this matters in a moment.
The Two-Node Quorum Problem
Before forming the cluster, there's something every Proxmox operator needs to understand about two-node clusters: without a tiebreaker, two nodes is worse than one node.
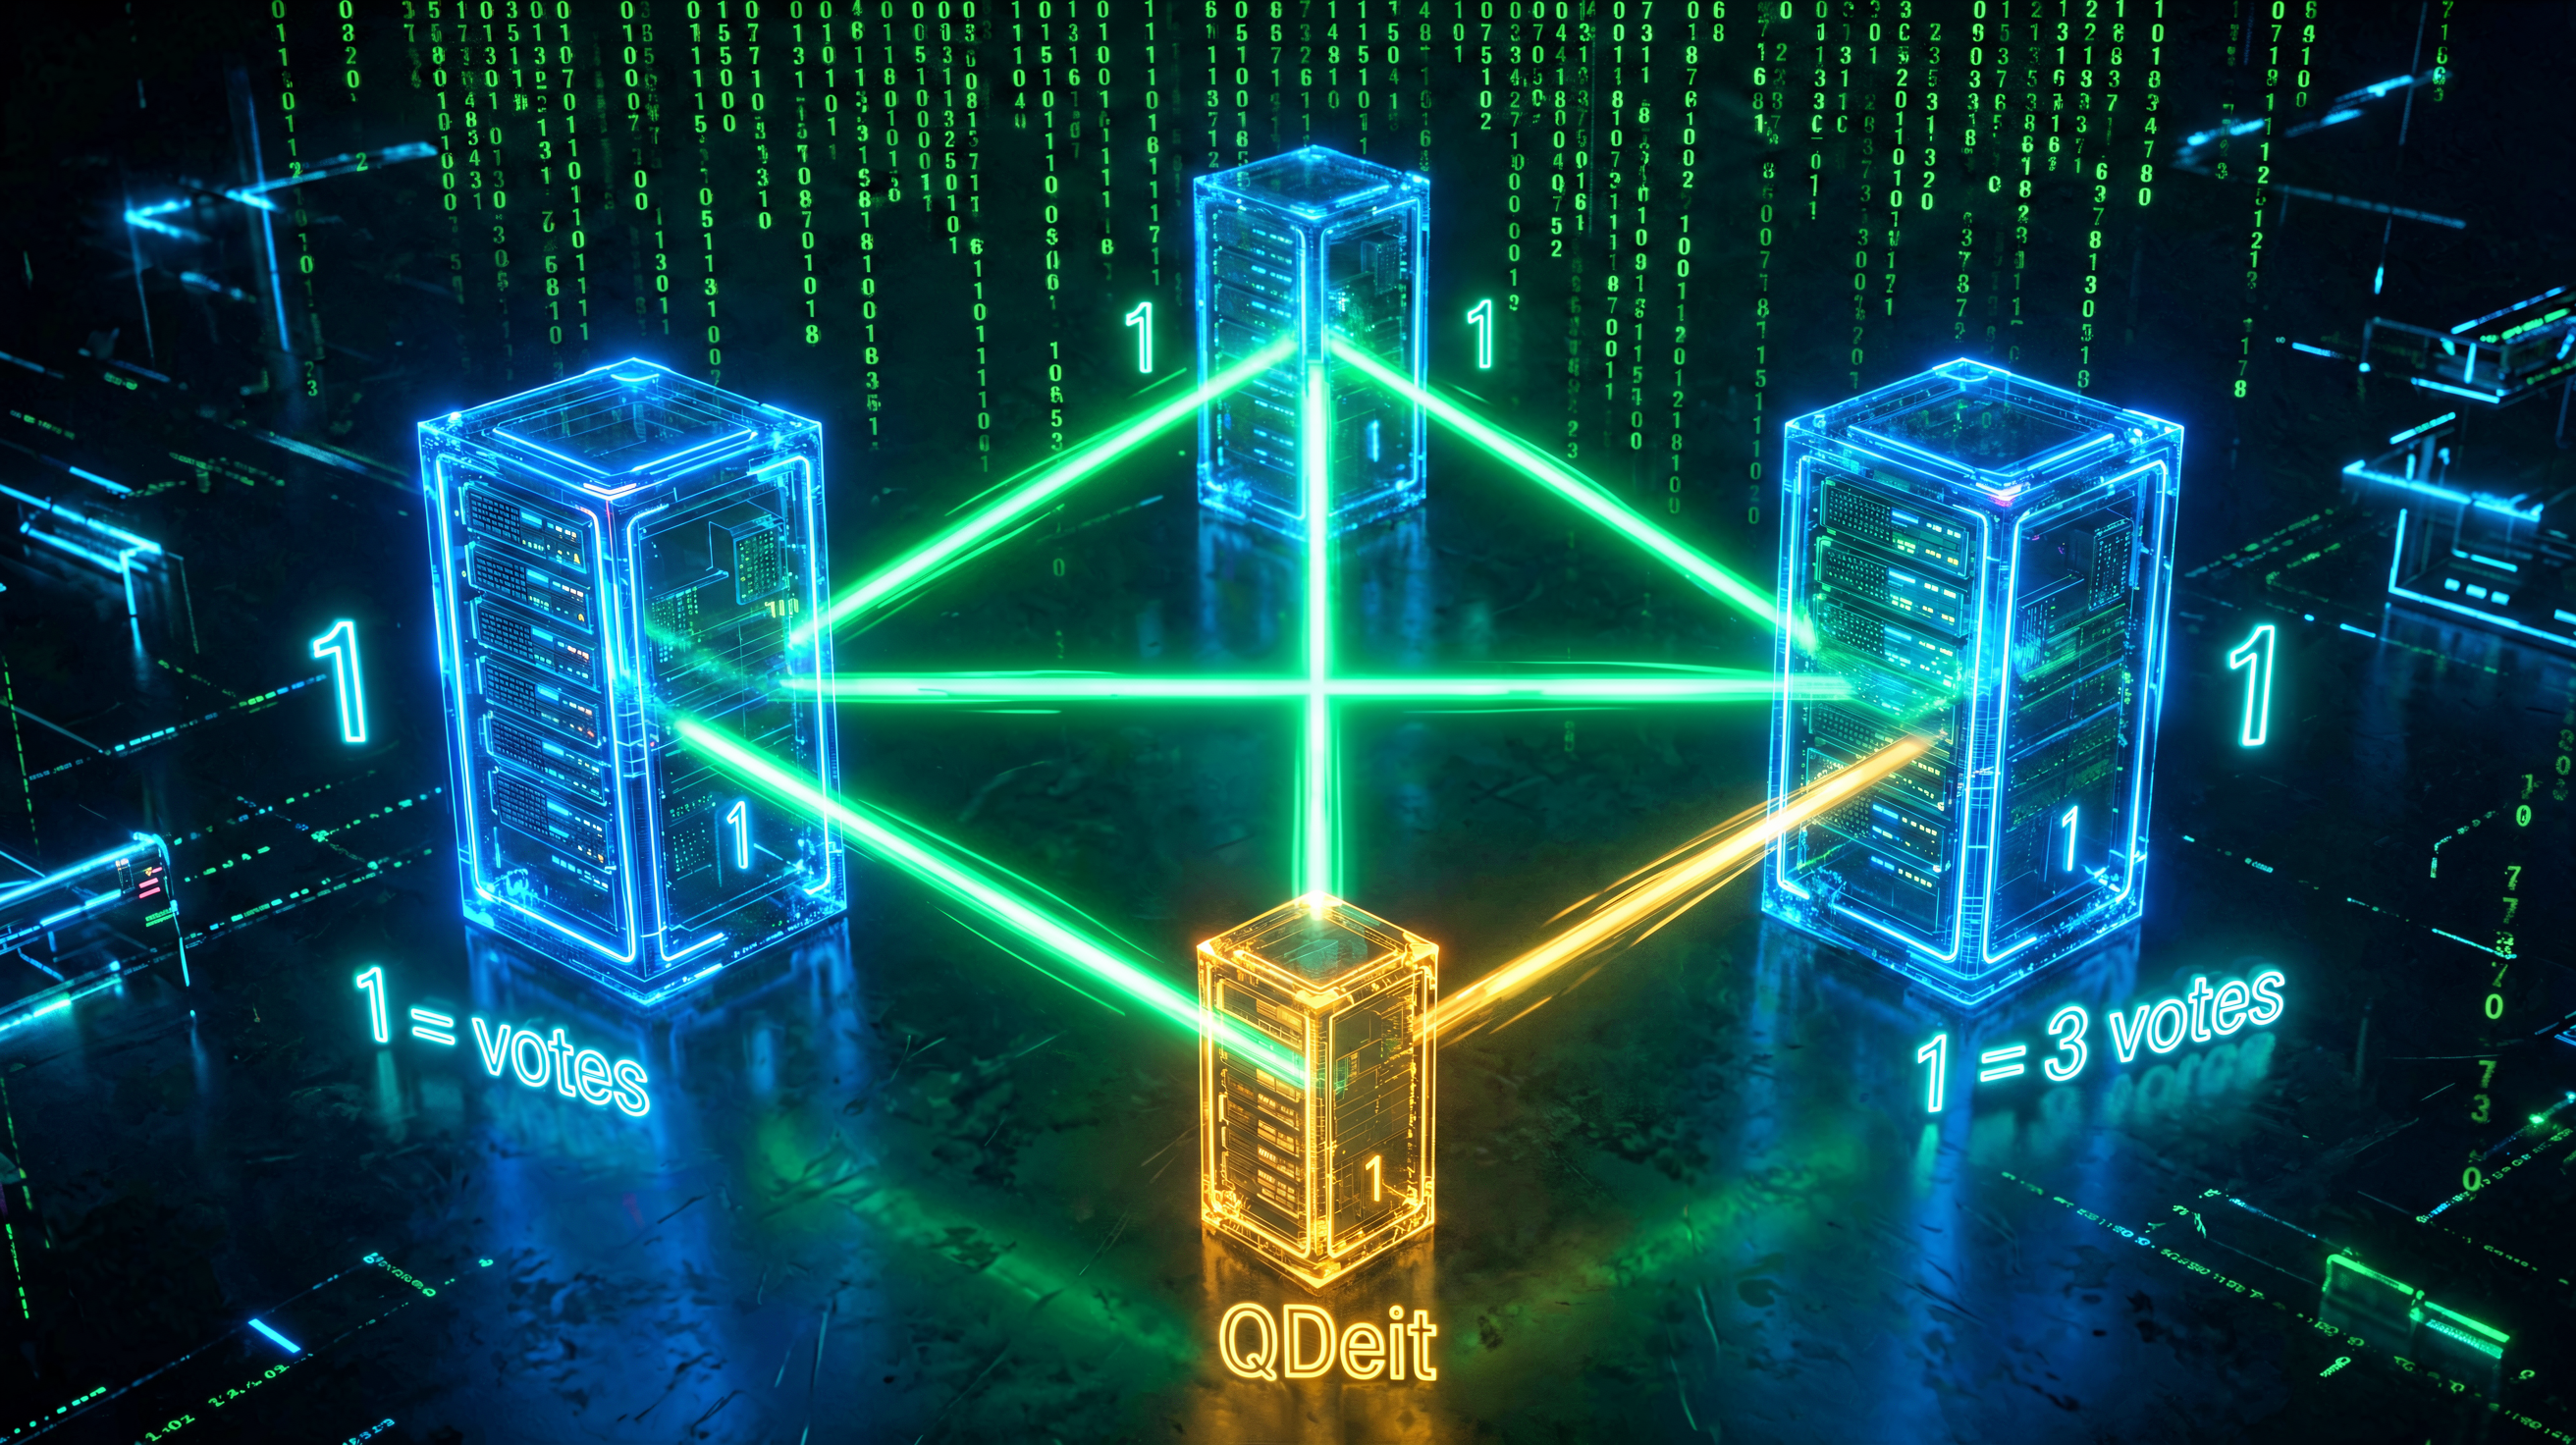
Proxmox uses Corosync for cluster membership, which requires quorum — a majority agreement among members. With two nodes, each holding one vote, you only have 2 total votes. If either node goes offline (even for a reboot), the surviving node has 1 vote out of 2 — no majority — and fences itself. Your services go down on the surviving node, which is the exact opposite of HA.
The solution is a QDevice: a lightweight third voter that breaks ties. It doesn't run any VMs or CTs — it just participates in quorum decisions. The maths:
pve (1 vote) + pve2 (1 vote) + QDevice (1 vote) = 3 total
Any single node failure → 2 remaining votes → quorum maintained ✅
For my QDevice, I used my Unraid NAS. It's always on, it's local LAN (no Tailscale latency), and it runs Docker — so deploying a corosync-qnetd container was straightforward. The catch: the mgrzybek/corosync-qnetd image that every tutorial references is no longer on Docker Hub. You have to build it yourself:
mkdir -p /tmp/qnetd-build
cat > /tmp/qnetd-build/Dockerfile << 'EOF'
FROM debian:bookworm-slim
RUN apt-get update && apt-get install -y corosync-qnetd && rm -rf /var/lib/apt/lists/*
RUN mkdir -p /etc/corosync/qnetd/nssdb
EXPOSE 5403
CMD ["/usr/bin/corosync-qnetd", "-f"]
EOF
docker build -t corosync-qnetd /tmp/qnetd-build/

# Initialise the NSS cert database first
docker run --rm -v /etc/corosync/qnetd:/etc/corosync/qnetd \
  corosync-qnetd /usr/bin/corosync-qnetd-certutil -i

# Start the container with both /tmp and cert dir mounted
docker run -d --name corosync-qnetd \
  --restart=unless-stopped \
  -p 5403:5403 \
  -v /etc/corosync/qnetd:/etc/corosync/qnetd \
  -v /tmp:/tmp \
corosync-qnetd /usr/bin/corosync-qnetd -fNSS error (-8174): bad database. And you must mount /tmp from the host — pvecm qdevice setup SCPs cert files to the host's /tmp before calling certutil inside Docker, and without the volume mount the exchange fails silently.
You also need to install corosync-qdevice on both Proxmox nodes before running pvecm qdevice setup — it provides corosync-qdevice-net-certutil which the setup command calls:
# On both pve and pve2
apt install -y corosync-qdevice
Forming the Cluster
The cluster formation order matters. QDevice must be set up before pve2 joins, because the cert exchange assumes an existing cluster on the source node:
# 1. Create the cluster on pve
pvecm create homelab-cluster

# 2. Set up QDevice (while still single-node)
pvecm qdevice setup 192.168.20.200 -f

# 3. Join pve2 via the web UI
# pve UI → Datacenter → Cluster → Join Information → copy
# pve2 UI → Datacenter → Cluster → Join Cluster → paste + pve root password

# 4. Verify 3 votes
pvecm status
When it's working, pvecm status shows this:
Membership information
----------------------
    Nodeid      Votes    Qdevice Name
0x00000001          1    A,V,NMW 192.168.20.99 (local)
0x00000002          1    A,V,NMW 192.168.20.97
0x00000000          1            Qdevice
A,V,NMW = Alive, Voting, Not Master Weight. Both nodes voting, one QDevice. Three total votes, quorum at 2. Any single failure is safe.
The IP Conflict I Didn't See Coming
I had originally assigned pve2 the IP 192.168.20.98. Only after the cluster was formed did I realise that .98 was already taken — by the PBS VM running on Unraid. Lesson: always scan the ARP table before assigning new IPs in a homelab. I checked from pve with arp -n to see what was actually in use.
Changing a node's IP after cluster formation requires updating several places in the right order: /etc/network/interfaces, /etc/corosync/corosync.conf on both nodes, then restarting corosync on both. The SSL cert embedded in /etc/pve/local/pve-ssl.pem also contains the IP, so you need to regenerate it with pvecm updatecerts --force — but the auto-update command reads from the running corosync config, so fix corosync first.
The Storage Architecture
This is the part that took the most thinking. Proxmox replication — the mechanism that makes HA possible for local-disk guests — only works with ZFS storage. LVM-thin, which my original setup used for almost everything, cannot be replicated. That's a hard constraint in the codebase, not a configuration option.
I had two options: reinstall Proxmox on pve from scratch with ZFS, or find a cleverer path. I found a cleverer path.
The Pool Rename Pivot
My plan was to wipe the SATA SSD on pve (256 GB Samsung) and create a ZFS pool there, while keeping the OS on the NVMe. This would give me:
- ZFS pool on SATA SSD for CT/VM storage (replicable to pve2)
- NVMe for OS + empty LVM pool (clean slate)
The catch: Proxmox replication requires the same storage ID on both nodes. My pve2 had its ZFS pool named rpool (the Proxmox installer default). If I created a pool named anything else on pve, replication would fail because the storage configuration is cluster-wide and can only hold one pool path per ID.
Rather than reinstalling pve2 just to rename its pool, I renamed pve's new pool to match:
# After emptying the SSD of all CT disks...
pvesm remove ssd-zfs          # remove old storage from Proxmox
zpool export ssd-zfs          # export the pool
zpool import -d /dev/disk/by-id/ ssd-zfs rpool  # reimport with new name
pvesm add zfspool rpool --pool rpool --content images,rootdir
Both nodes now have a ZFS pool named rpool. Replication can proceed.
The Two-Tier HA Strategy
Not every service needs the same HA approach. I split my CTs into two tiers based on their relationship to Unraid:
| Tier | Services | Storage | HA mechanism |
|---|---|---|---|
| Critical | adguard, caddy, hermes-vm, scrypted, utilities, unbound | rpool ZFS | ZFS replication → HA failover (~1-2 min) |
| Media | arrstack, media-servers, telegram-bot | proxmox-ha NFS | Shared NFS HA (Unraid cache SSD) |
The critical services have zero Unraid dependency — they should survive even if the NAS is down. Moving their root disks to Unraid NFS would make Unraid a single point of failure for DNS and the reverse proxy, which defeats the purpose. ZFS replication is the right answer here.
The media CTs are already Unraid-dependent. Their actual data — movies, series, media files — lives on Unraid NFS. If Unraid goes down, these services can't function regardless of where their root disk lives. So I moved their root disks to a dedicated NFS share on Unraid's cache SSD (proxmox-ha, set to cache-only so it never moves to spinning disks), and both cluster nodes mount it. Proxmox can restart these CTs on either node automatically because both can reach the disk over NFS.
Setting Up ZFS Replication
With both nodes having a rpool storage and pve2 also having rpool/data as a receive target (created as a dataset under the default rpool), I created replication jobs in Proxmox:
# One job per guest, 5-minute schedule
pvesh create /cluster/replication \
  --id 101-0 --target pve2 --type local --schedule '*/5'
# Repeat for 100, 102, 106, 108, 110
The first sync copies the full ZFS dataset to pve2. Subsequent syncs are incremental — they only send the delta since the last snapshot. Once established, my incremental syncs run in around 2 seconds each. The initial syncs ranged from a few seconds (small CTs) to ~2.5 minutes for hermes-vm at 41 GB.
The Privileged Container Freeze Problem
One CT gave me trouble: CT108 (utilities), which is a privileged container running Docker. Proxmox replication freezes the guest filesystem briefly before taking a ZFS snapshot to ensure consistency. For unprivileged containers this works fine. For a privileged container with Docker's overlay mounts, the freeze call hangs indefinitely — Docker doesn't respond to the LXC freeze mechanism, and pvesr run just blocks with no timeout.
The workaround: stop the container for the initial sync, then start it again. Subsequent incremental syncs are brief enough that the freeze window (a fraction of a second) completes before Docker's overlay has time to cause problems.
# For CT108 initial sync only:
pct stop 108
pvesr schedule-now 108-0
# Wait for sync to complete...
pct start 108
Enabling HA
With replication running and datasets present on pve2, enabling HA is anticlimactic — it's just a few commands:
ha-manager add ct:101 --state started --max_restart 3 --max_relocate 3
ha-manager add ct:102 --state started --max_restart 3 --max_relocate 3
# ...and so on for all guests
The HA manager arms the corosync watchdog, starts monitoring heartbeats, and will restart any managed resource on the surviving node if its primary node goes offline. The fencing armed line in ha-manager status is the signal that it's live:
quorum OK
master pve2 (active, ...)
fencing armed (CRM watchdog active)
lrm pve (active, watchdog active)
lrm pve2 (active, watchdog active)
service ct:101 (pve, started)
service ct:102 (pve, started)
service vm:100 (pve, started)
...
Gotchas Along the Way
A few things that burned time and are worth documenting:
The ct105-watchdog loop. After migrating CT105 (telegram-bot) to pve2, I noticed hastart tasks firing every two minutes in the Proxmox task log. The culprit: a ct105-watchdog.service systemd timer I had created months earlier as a one-off workaround to auto-restart CT105 if NFS dropped. The watchdog called pct start 105 on pve — which pve could no longer see (the config had moved to pve2) — and the HA manager treated each call as a start request. Fix: systemctl disable --now ct105-watchdog.
The NFS health worker needed a cluster-aware patch. I run a custom NFS health worker on pve that auto-starts CTs with onboot=1 if NFS comes back healthy after a dropout. After clustering, this worker would try to start CTs that now live on pve2 — their LXC config files don't exist on pve anymore, but the worker iterated over all VMIDs it knew about. I patched start_ct_if_ready() on both nodes to check for a local config file before attempting a start:
# Skip CTs that have no config on this node (they live on the other node)
[ ! -f "/etc/pve/nodes/$(hostname -s)/lxc/${ct}.conf" ] && return 0
The stale pvesr.lck. ZFS replication uses a global lock file at /var/lock/pvesr.lck. If a replication run dies mid-job (which happened a few times during the PBS backup window), the lock file persists and blocks all subsequent replication runs indefinitely. The fix is just rm -f /var/lock/pvesr.lck, but it's not obvious why all your replication jobs suddenly show "pending" and never progress.
The storage ID naming constraint. Proxmox replication requires both nodes to have a storage entry with the exact same ID pointing to a ZFS pool. The storage config is cluster-wide (stored in pmxcfs), so you can't have different pool paths for the same ID per node. Both nodes must have identically named ZFS pools. This is why the pool rename was necessary — and why it's worth setting the ZFS pool name explicitly during install instead of accepting the default rpool blindly.
The Final Architecture
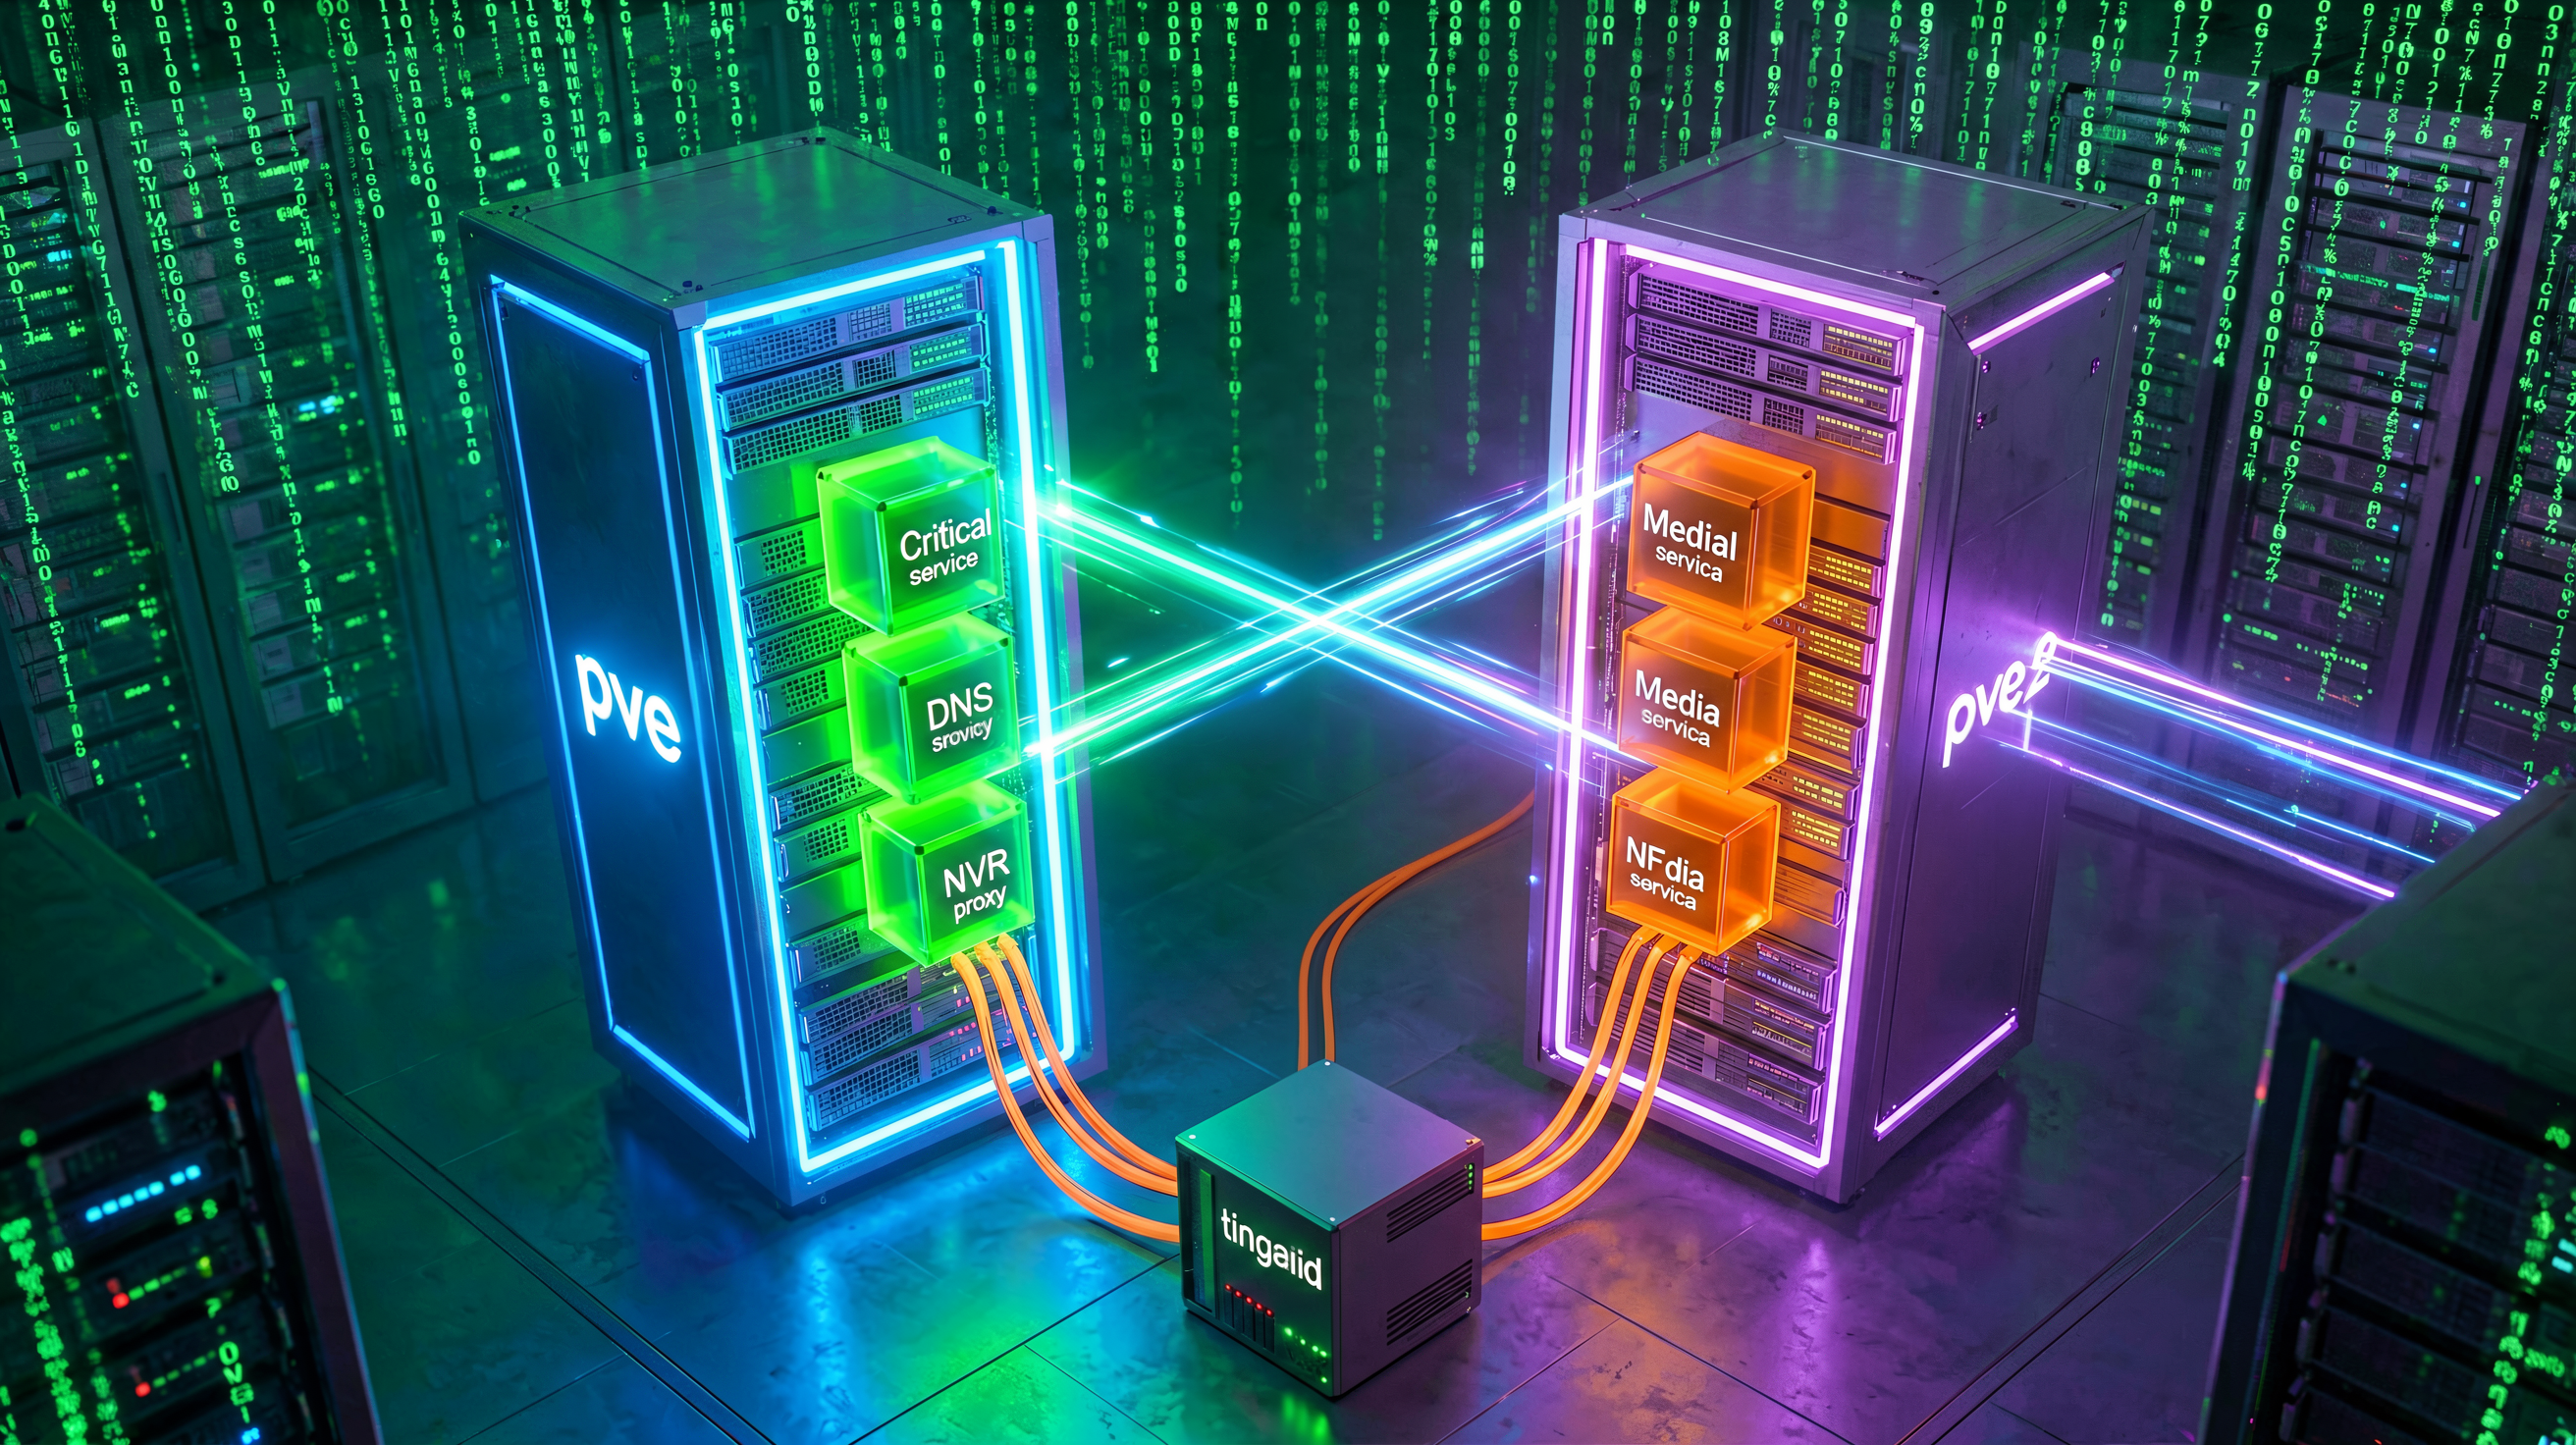
After a very long day, this is where everything landed:
| Resource | Primary node | Failover | Storage |
|---|---|---|---|
| VM100 hermes-vm | pve | pve2 | rpool ZFS + replication |
| CT101 adguard | pve | pve2 | rpool ZFS + replication |
| CT102 caddy | pve | pve2 | rpool ZFS + replication |
| CT106 scrypted | pve | pve2 | rpool ZFS + replication |
| CT108 utilities | pve2 | pve | rpool ZFS + replication |
| CT110 unbound | pve | pve2 | rpool ZFS + replication |
| CT103 media-servers | pve2 | pve | proxmox-ha NFS (Unraid) |
| CT105 telegram-bot | pve2 | pve | proxmox-ha NFS (Unraid) |
| CT107 arrstack | pve2 | pve | proxmox-ha NFS (Unraid) |
ZFS replication runs every 5 minutes. Incremental syncs take about 2 seconds once established. If pve's hardware fails, pve2 will restart the critical services (DNS, reverse proxy, Hermes, NVR) automatically within 1–2 minutes. No manual intervention required.
Was It Worth It?
The question I asked myself throughout this was: am I over-engineering a homelab? The honest answer is that it depends entirely on how much you rely on it.
If Hermes (my AI agent) goes down, my daily workflows break. If AdGuard goes down, nothing on my LAN resolves DNS. If Caddy goes down, none of my self-hosted services are reachable. These aren't just nice-to-haves anymore — they're infrastructure I depend on every day. At that level of reliance, HA stops being over-engineering and starts being basic operational hygiene.
The disk failure taught me that I had been lucky, not good. Building HA was removing risk that had been silently accumulating while I optimistically assumed nothing would break. The whole point is to do this before the incident, not after.
The cluster, the QDevice, the ZFS replication, the HA policies — none of it is glamorous. Most of the day was spent on edge cases: wrong pool names, stale lock files, cert IP mismatches, a rogue watchdog service. But the result is a homelab that can lose a node and keep running. That's worth a lot of patience.